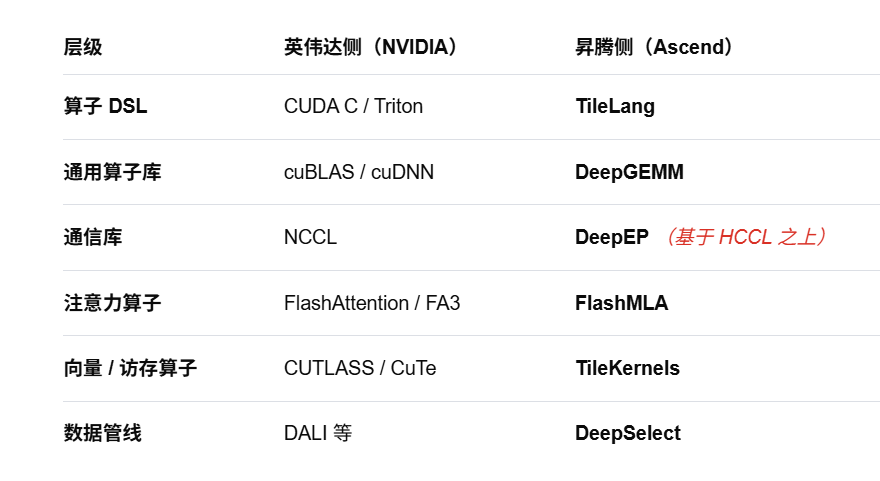
DeepSeek has open sourced a bundle of operator tools and, together with Huawei Ascend, is taking aim at Nvidia’s CUDA lock in. The release centres on TileLang, a language for writing the low level operators that actually run on silicon.
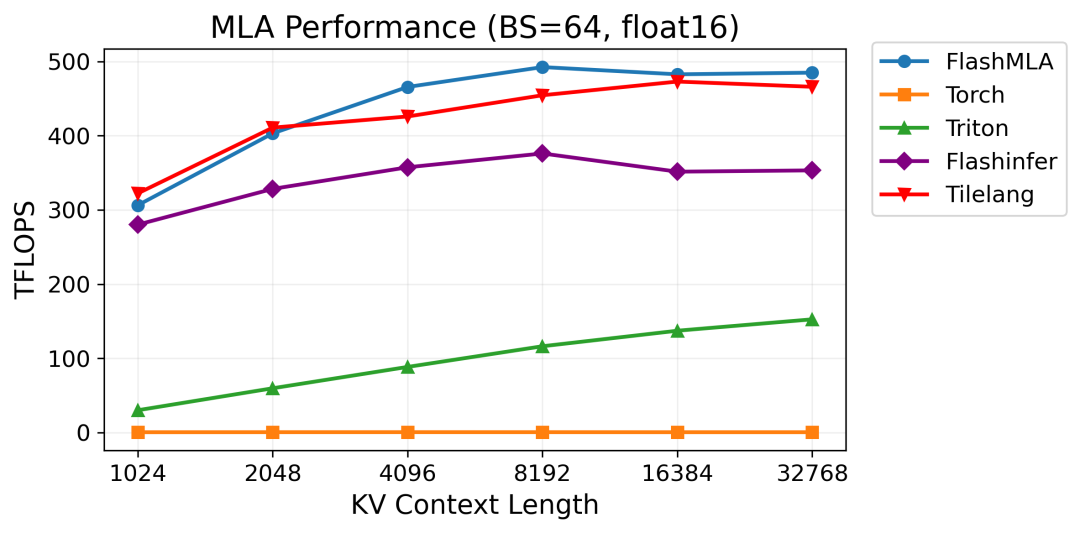
The age of handcrafting operators in a workshop should end. Writing operators today means tuning each chip by hand, slow and hard to reuse. TileLang, built on top of TVM, claims to land in the global first tier on performance.
The architecture splits cleanly. A target backend defines only that chip’s instruction syntax and optimisation rules, the hardware specific part. An execution backend handles the generic compile, load and launch flow, independent of the hardware. One codebase can therefore run across many chips.
Storage control decides where data lives. A chip has three memory tiers: global memory is largest but slowest, shared memory is medium, registers are smallest but fastest. TileLang lets a developer decide in Python which tier holds what, so compute units never stall waiting for data.
Thread scheduling decides how work is split. One line partitions a huge matrix compute like a grid, assigning it precisely across thousands of cores on the chip, for example 100 task blocks of 128 concurrent threads each, running in parallel.
Parallel rhythm controls transfer and compute together. A single T.Pipelined call with three stages opens a three stage software pipeline, letting data movement and computation overlap so the chip is never idle.
The strategic bet is Huawei Ascend. By making one operator language portable across Ascend, Nvidia and domestic silicon without rewrites, DeepSeek is attacking the moat Nvidia built through CUDA from the bottom up.
Editor’s note: This is an adapted translation of the original Leiphone report. It has been trimmed and restructured for readability for an international business audience. The full original (in Chinese) is at https://www.leiphone.com/category/yanxishe/UUIfK7eeFE9Ws1JI.html.